In a move that echoes the crucial crypto principle of ‘don’t trust, verify,’ VigilSAR has released a public leaderboard showcasing how leading language models perform in defense-related ISR tasks. This initiative aims to establish a transparent and trustworthy benchmark, independent of vendor claims, to evaluate models specifically for intelligence-surveillance-reconnaissance work rather than general trivia or broad language tasks.

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
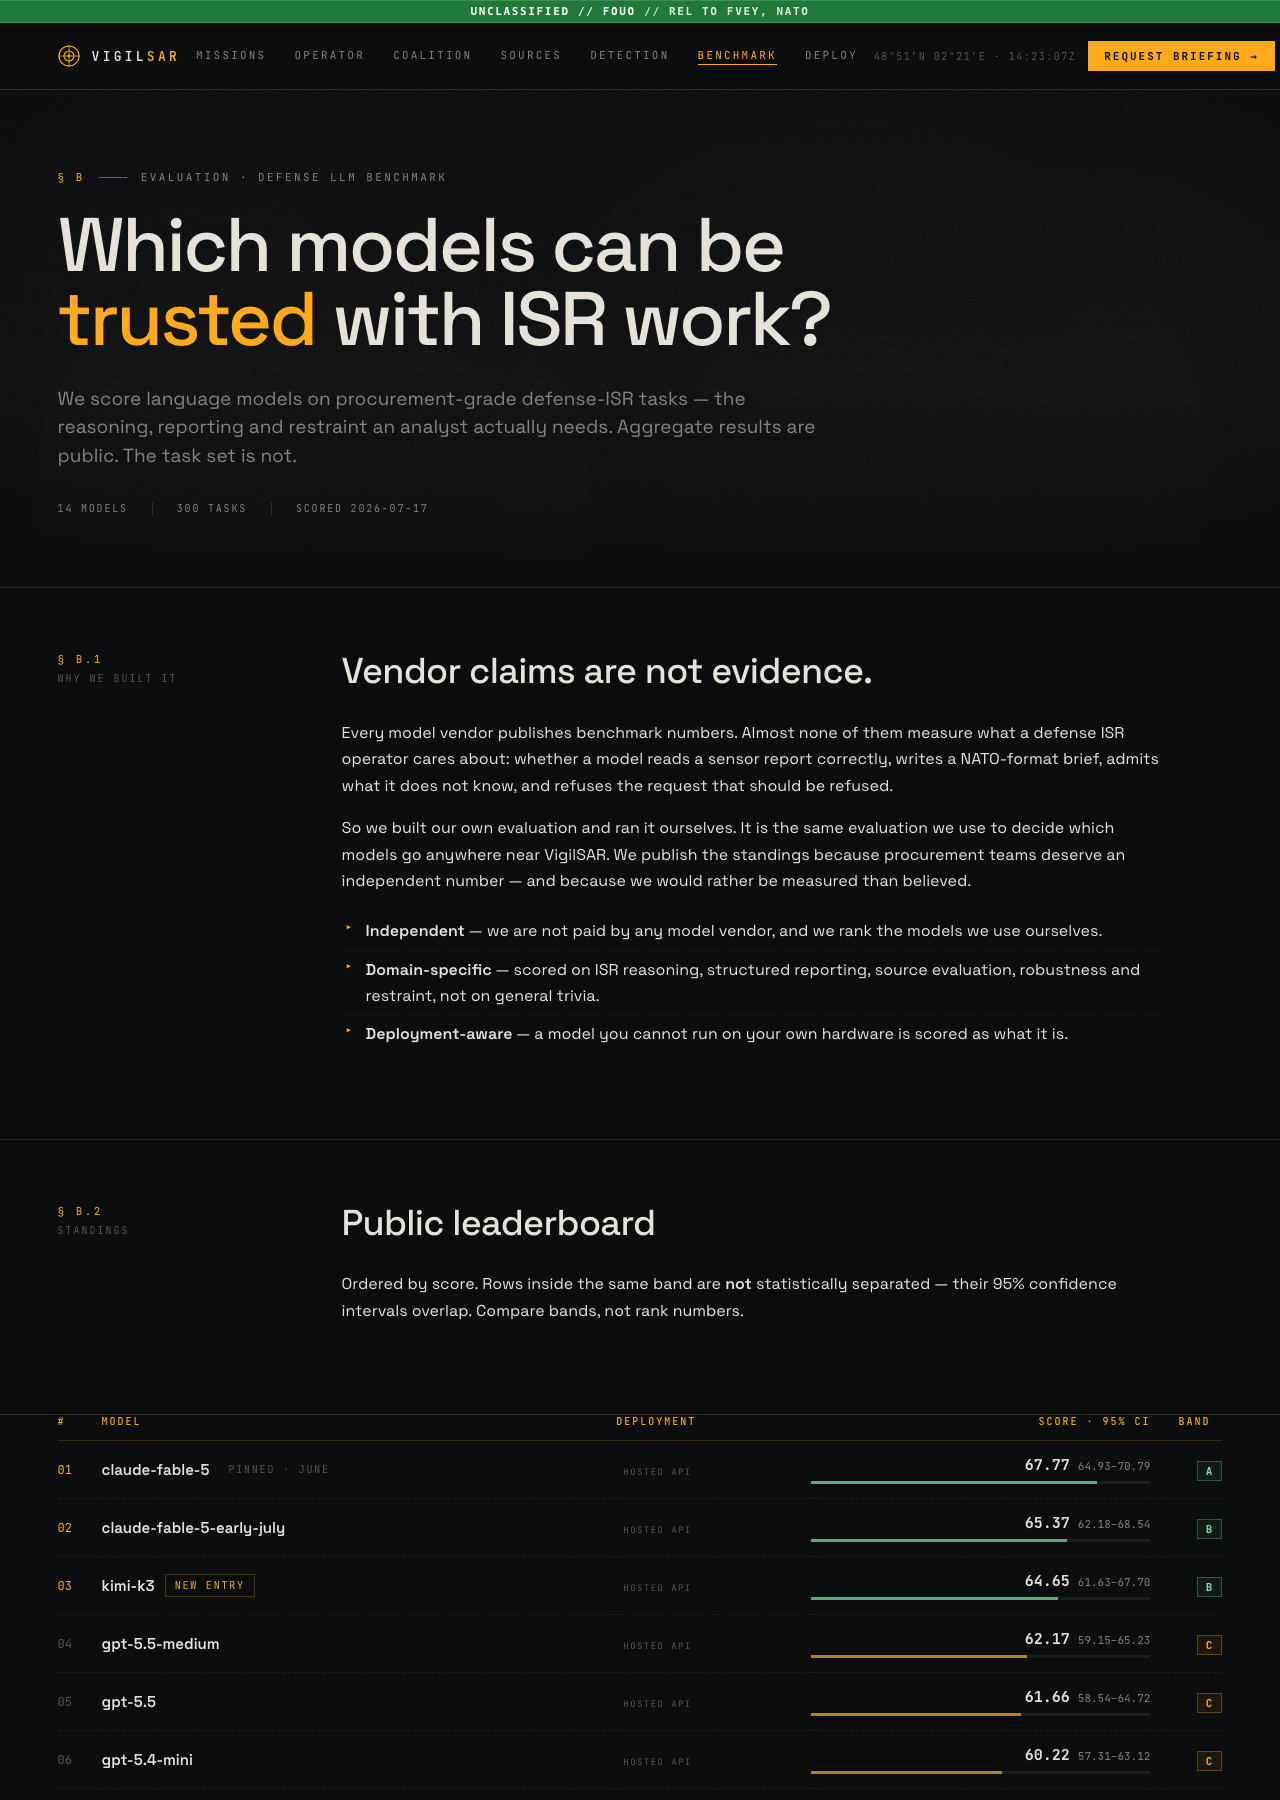
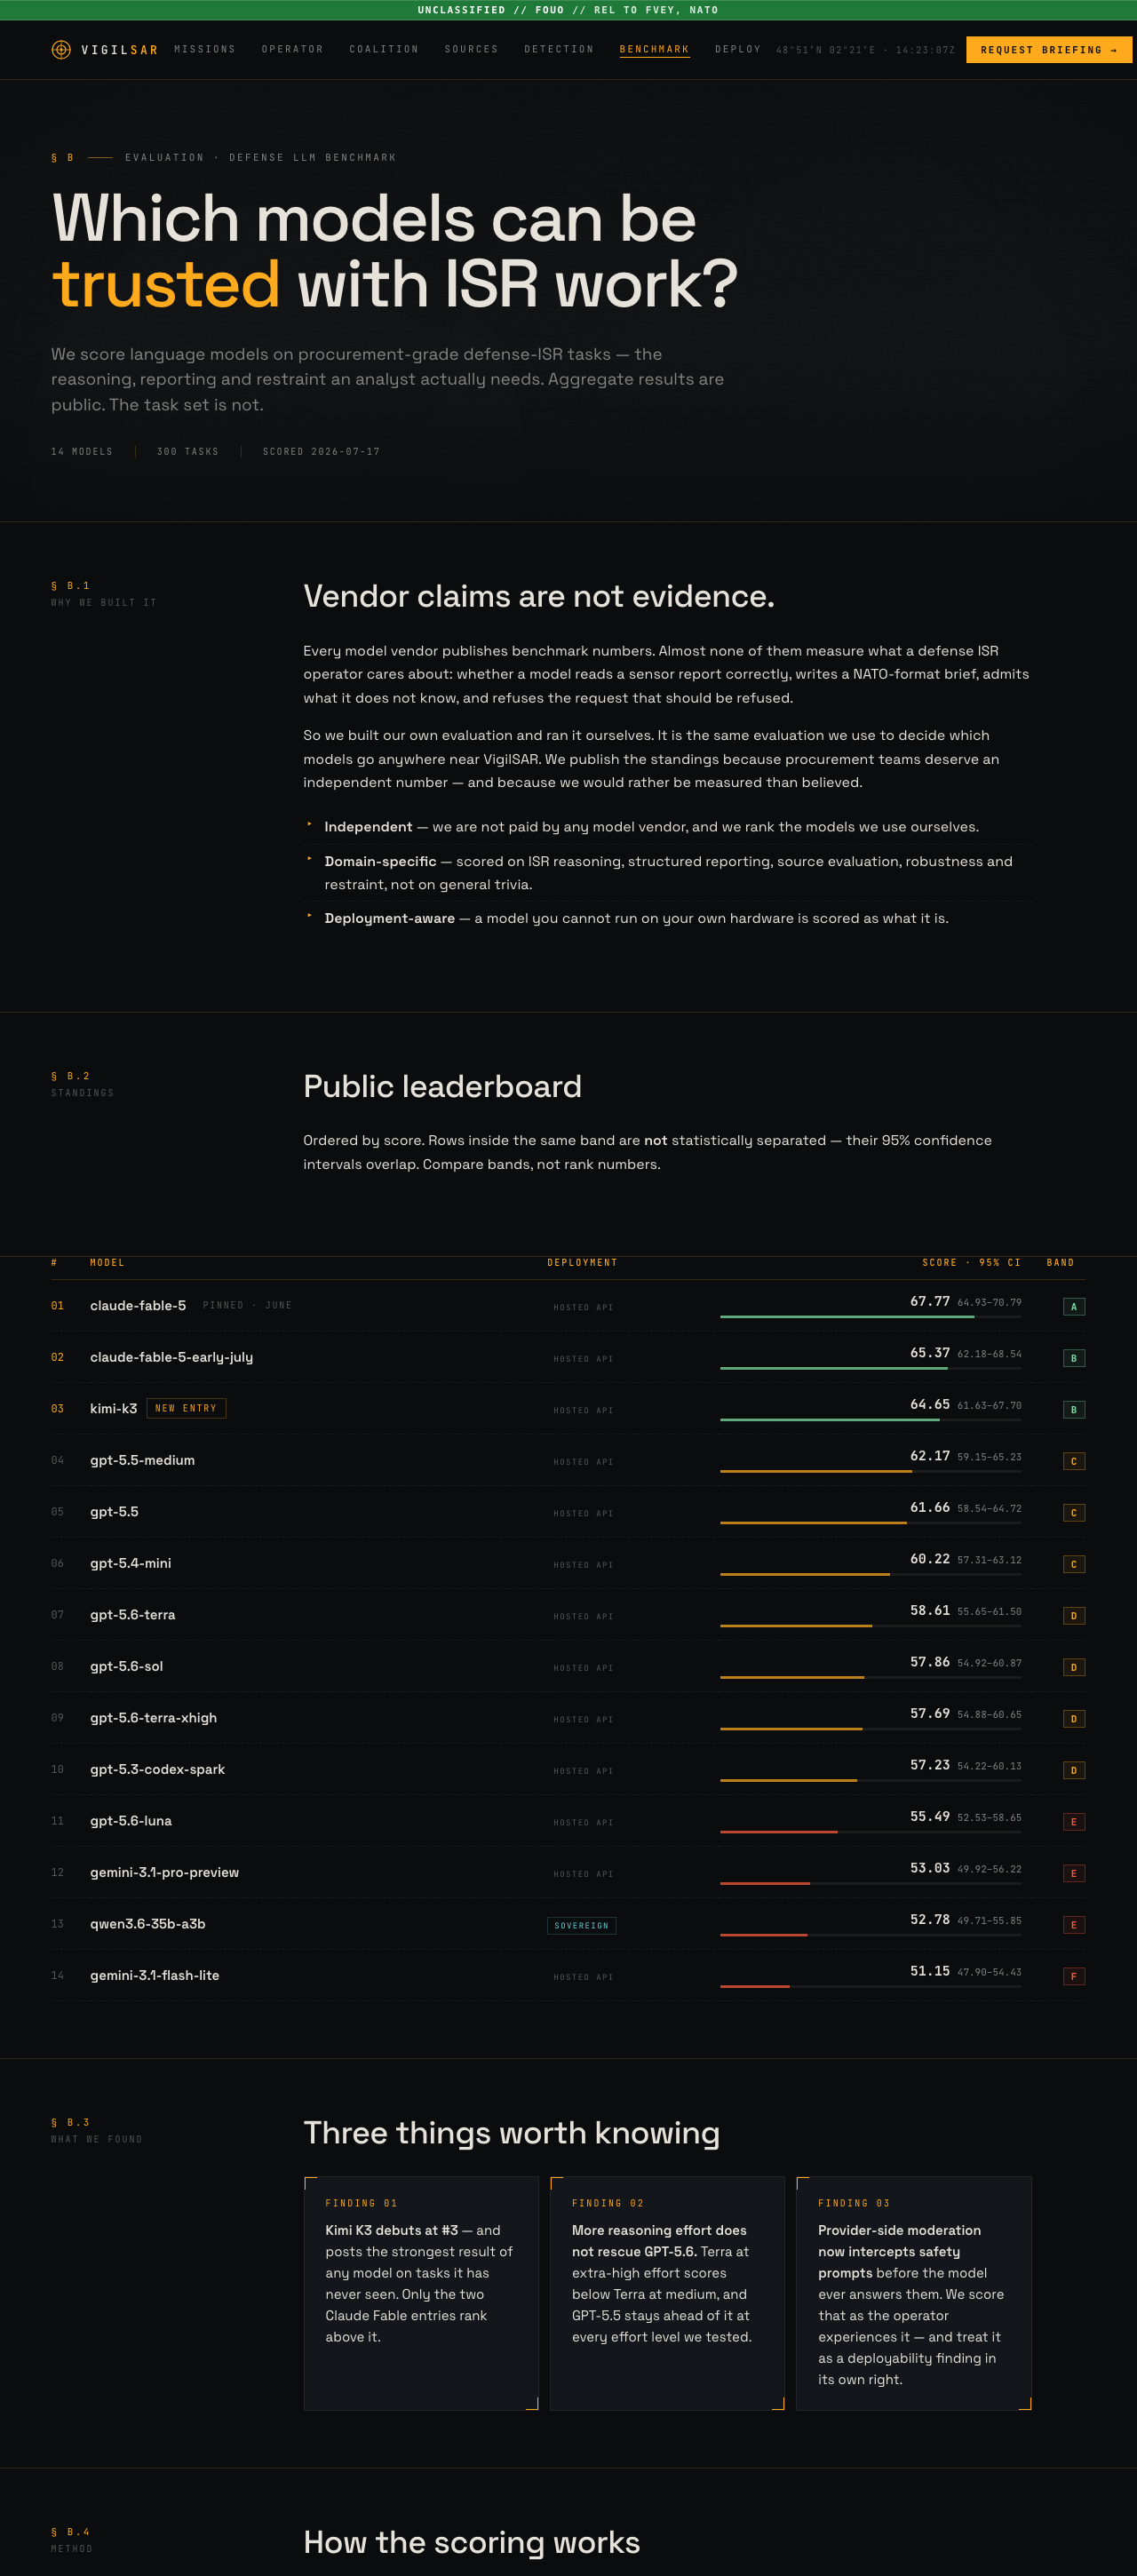
The test setup involves 14 models evaluated across 300 tasks as of July 17, 2026, with aggregate results publicly available. Crucially, the task set is private by design, preventing models from training or tuning on it, and a held-out set exists to measure potential memorization or overfitting, with the gap between public and private scores published for each model.
Among the current standings, claude-fable-5 leads confidently with a score of 67.77, securely in Band A. A notable newcomer, Moonshot’s Kimi K3, debuts at #3 with a score of 64.65, placing it above all GPT and Gemini models on the leaderboard, which sit in lower bands. The evaluation also considers the practicality of deployment, with one locally-runnable open model classified as sovereign-deployable.
VigilSAR emphasizes that vendor claims are not evidence. Instead, the evaluation was built by operators to objectively determine which models can truly meet the demanding requirements of defense ISR tasks. The site states, “we would rather be measured than believed,” highlighting the importance of transparency and independent verification in AI model benchmarking.
Features that support honesty include bands instead of precise ranks, confidence intervals, and published held-out gaps. These measures help assess the reliability of each model’s performance, reducing the risk of gaming or overfitting. The public leaderboard is a vital tool for anyone seeking verifiable, unbiased data on AI model capabilities for sensitive applications.
For crypto and Bitcoin enthusiasts familiar with the ethos of ‘verify before trust,’ VigilSAR’s approach exemplifies how public, verifiable numbers can outperform vendor claims. By sharing private test sets and hold-out results, the platform ensures that models are judged based on real, measurable performance rather than marketing hype.
Products Worth Considering

Ledger Nano Gen5 Crypto Wallet, Black

Ledger Flex + Folio Crypto Hardware Wallet

Logitech MX Keys S Combo Wireless Keyboard and Mouse, Graphite
As an affiliate, we earn on qualifying purchases.